If you've ever tried to edit an action sports video, you know the hardest part isn't the editing itself—it's the logging. Going through thousands of clips to find the three angles where a rider actually landed a trick cleanly takes hours.
Generic AI video editors are terrible at this. They look for talking heads or high-contrast scene changes. They don't know the difference between a tailwhip and a barspin, let alone the difference between a landed trick and a painful bail.
To solve this, I built a custom AI pipeline capable of searching, tagging, and categorizing thousands of raw BMX clips automatically.
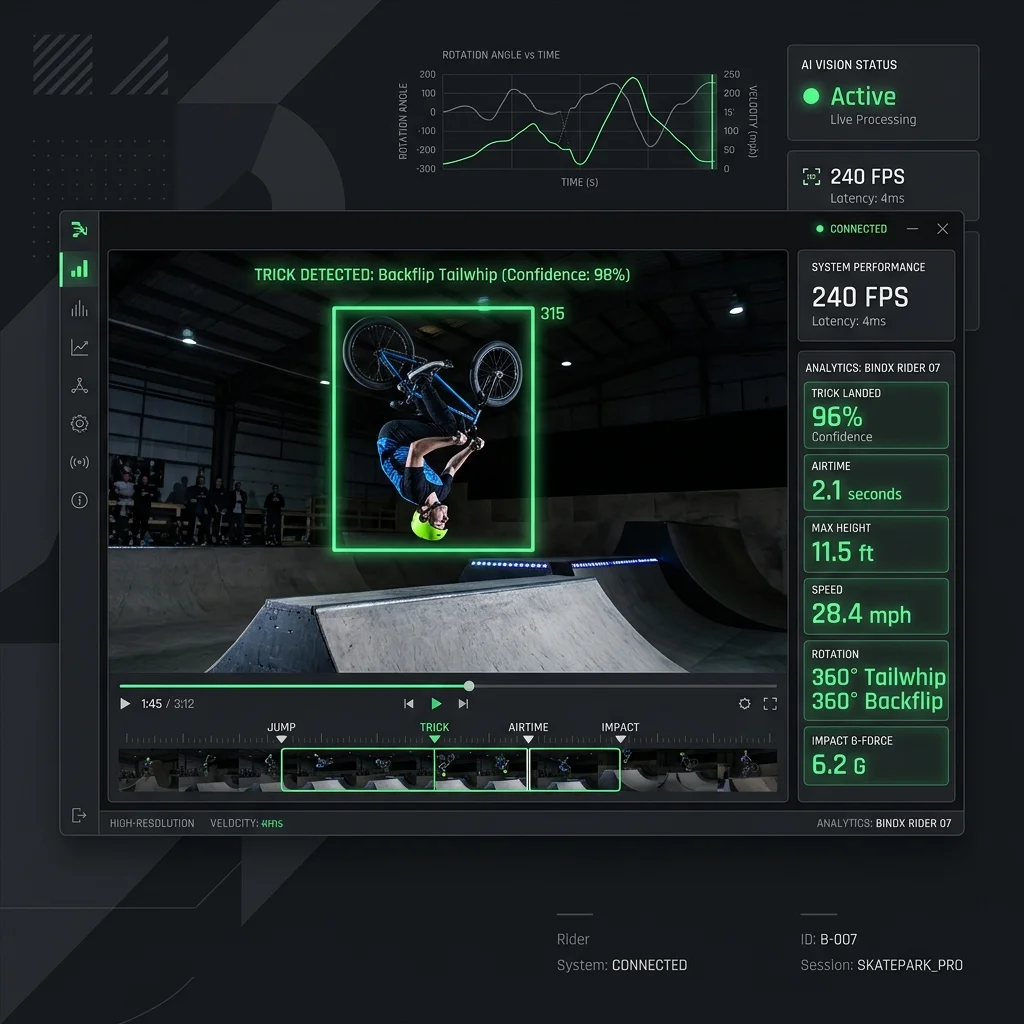
The Problem: 3,355 Raw Clips
When I started this project, I had an archive of over 3,000 raw BMX clips. My goal was to build a system that could answer queries like:
- "Find all clips of a 360 over a dirt jump, landed cleanly."
- "Find all bails on handrails."
Doing this required chaining together three distinct technologies: Computer Vision (YOLO), Audio Peak Analysis, and a Large Language Model for reasoning.
Step 1: Object and Scene Detection (YOLO)
The first pass of the pipeline runs a custom-trained YOLO (You Only Look Once) model. Standard object detection can find a "bicycle," but I needed it to find "BMX bike," "rider in air," "grind rail," and "dirt jump."
I fine-tuned a YOLOv8 model on a few hundred frames of BMX footage. As it processes a video, it logs the presence of these elements frame-by-frame into a JSON file.
Step 2: Finding the Action via Audio
Action sports have a very distinct audio signature. The sound of a pedal click, the snap of a bunnyhop, the loud clank of pegs on a rail, and the thud of landing (or crashing).
I wrote a C++ utility using FFmpeg that scans the audio track of each clip and logs the exact timestamp of peak audio events.
// Pseudocode for audio peak detection
std::vector<int> FindAudioPeaks(const std::string& filepath, double threshold) {
    // Decode audio stream
    // Calculate RMS volume per frame
    // If volume > threshold, log timestamp
    return peak_timestamps;
}
Step 3: LLM Reasoning and Tagging
This is where the magic happens. We now have a JSON file containing:
- When a rider and a rail were on screen.
- When the loudest impacts happened.
I feed this telemetry data into a local LLM, instructing it to act as an action sports judge. The prompt looks something like this:
"You are analyzing telemetry from a BMX clip. The rider approaches a rail at 00:03. A loud impact occurs at 00:04 (pegs hitting rail). Another impact occurs at 00:06 (landing). The rider remains on the bike and exits the frame at 00:08. Did they land the trick or bail?"
Because the telemetry clearly shows the rider continuing after the second impact, the LLM confidently tags it as [Status: Landed]. If the audio showed a massive impact followed by the bike and rider separating in the YOLO bounding boxes, it would tag it as [Status: Bail].
The Search Interface
All of this data is stored in a local SQLite database, indexed using vector embeddings for semantic search. Now, when I type "clean rail grinds," the system doesn't just guess—it queries the telemetry.
Domain knowledge matters. You can't just throw raw footage at a generic model and expect it to understand the nuances of a sport. But when you combine deterministic analysis (audio, bounding boxes) with agentic reasoning, you can index a lifetime of footage in an afternoon.